Overview
Created Aug. 5, 2025;
rev. 17 April 2026
This is a digital kit for exploring a collection of 553 journal articles published in English in 2024 that mention “artificial intelligence” or “AI” in their titles. These include the 227 “highly cited” such articles of that year in the Web of Science Core Collection index; and the 326 articles on AI in the Web of Science Arts & Humanities Citation Index (AHCI) (as listed on Feb. 15, 2025). Note †
The kit accompanies my article “AI Virtue: What is Good Knowledge in the Age of Artificial Intelligence?,” Modern Fiction Studies (forthcoming). The kit is thus focused on providing ways to study the language of epistemic values in discussions of AI (terms characterizing and evaluating the quality of knowledge, and its knowers, swirling all around AI—e.g., true, reliable, accurate, precise, nuanced, original, creative, and myriads of others). But the kit’s topic models and word embedding models can also be used to study other features of the article sets.
The kit, whose parts are listed in the table below, may be downloaded as a package in a .zip file deposited in the open-data Zenodo repository (https://doi.org/10.5281/zenodo.19264354). (I do not also put the kit in a GitHub repository because some data exceeds GitHub file size limits.)
For convenience, I also make most of the kit’s web pages, documents, data, and other materials (excluding too-large data files) directly accessible here on my personal website; see links in table of contents table below. The kit contains only non-consumptive use data about, and data models of, articles. It includes no full texts of materials under copyright.
The kit is published under a CC BY (Creative Commons Attribution 4.0 International) license.
How to Cite this Kit
- As presented on my personal website: Alan Liu, “Kit for Exploring Articles on AI Published in 2024,” Alan Liu (blog), 2025, https://alanyliu.org/citation/kit-for-exploring-articles-on-ai-published-in-2024
This presentation of my kit includes live HTML pages with visualization interfaces and other materials that can be accessed directly and individually downloaded or opened in a browser. However, the kit on my personal website excludes some data such as large topic model data files; and, of course, a personal website is not designed for archival permanence.
- Full .zip archive (with all data) permanently deposited in Zenodo: Alan Liu, “Kit for Exploring Articles on AI Published in 2024,” Zenodo, 2025, https://doi.org/10.5281/zenodo.19264354.
This zip file contains all data and documents in the kit. If updated, the zip file will be versioned in Zenodo with separate DOI’s that can be cited individually if needed.
Kit Table of Contents
Many parts of the kit of interest to the general user are directly accessible from links below. For the entire kit, download the .zip file.
| Folder |
Description |
Primary Item Types & Formats
(Links go to materials on alanyliu.org website. For full kit, with all data, download the .zip file) |
Tips for the General User |
| 0 |
“Readme” File (including overview, table of contents, statement of limitations) |
Main Readme:
|
|
| 1 |
Article Lists: Bibliographies and spreadsheets of articles in my corpora of 553 English-language articles published in 2024 mentioning “artificial intelligence” or “AI” in their titles as identified in:
- Web of Science Core Collection citation index (227 “highly cited” articles)
- Web of Science Humanities Citation Index (AHCI) (326 articles)
Folder 1’s Readme includes an explanation of my search parameters in Web of Science.
|
Folder 1 Readme:
Bibliographies:
Article list spreadsheets with file numbers in my corpora:
|
The bibliographies are of most general use.
But the article list spreadsheets with file numbers in my corpora are helpful when consulting my topic model “summaries” (in folder 2), where top documents associated with any topic are keyed to my corpus file numbers. The spreadsheets also include details about citation sources in the Web of Science.
|
|
| 2 |
Topic Models:
Subfolders:
- wos_core_topicmodel_22topics
- wos_ahci_topicmodel_22topics
- wos_ahci_topicmodel_40topics
Each subfolder contains a spreadsheet summarizing a topic model, the Mallet data files for the model, and DFR Browser 2 and pyLDAvis interactive visualizations of the model.
|
Folder 2 Readme(s):
Mallet data files:
Model summaries–spreadsheets with descriptive topic labels, top keywords, top docs:
Interactive visualizations:
|
Model summaries provide mid-level abstractions of the topic model data. They also include descriptive topic labels suggested by AI.
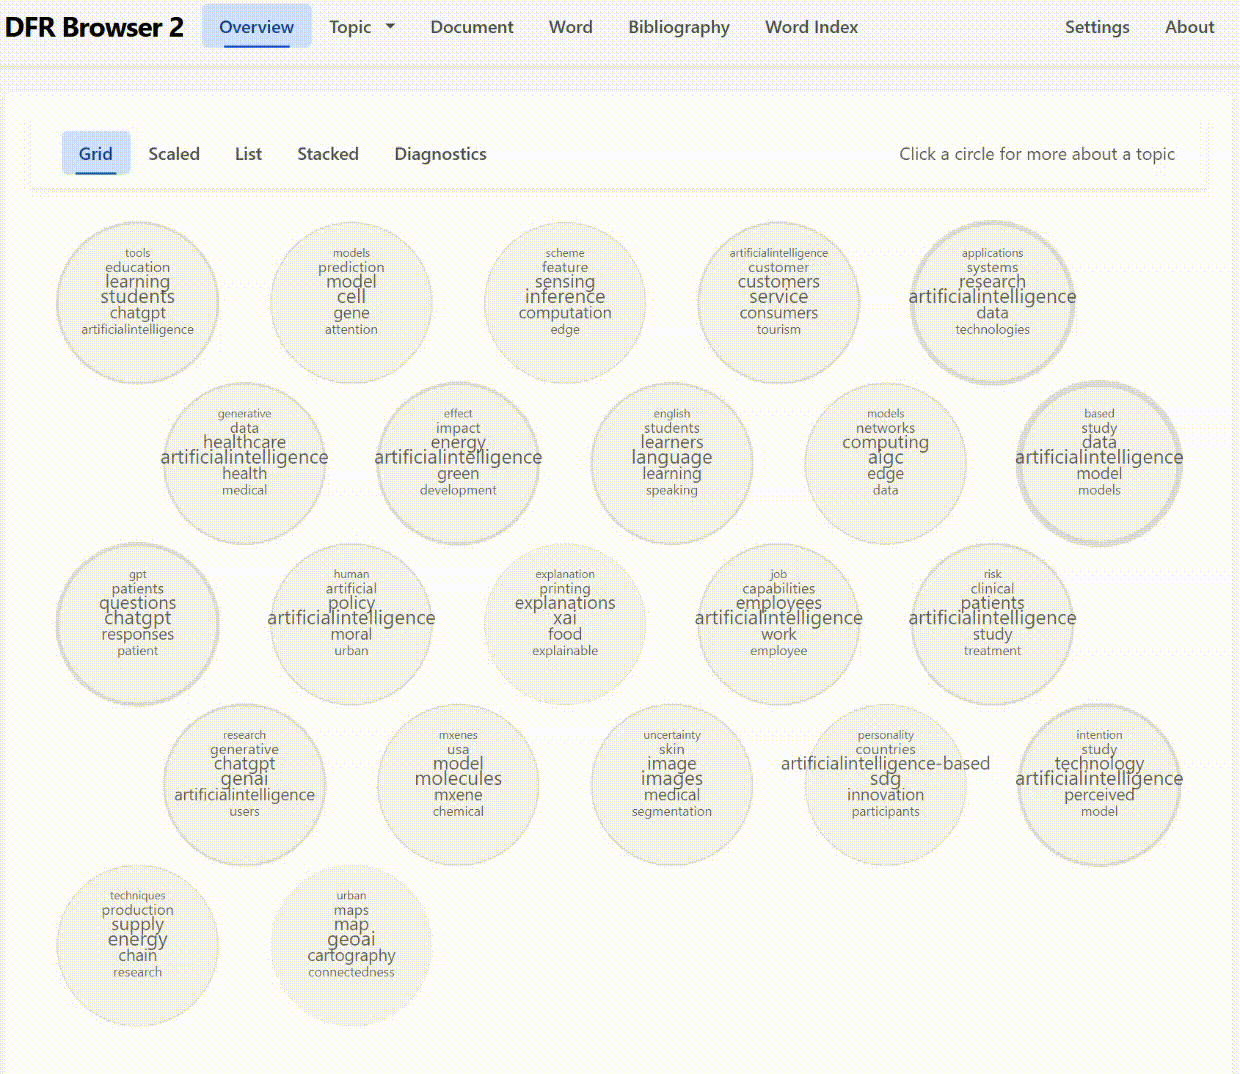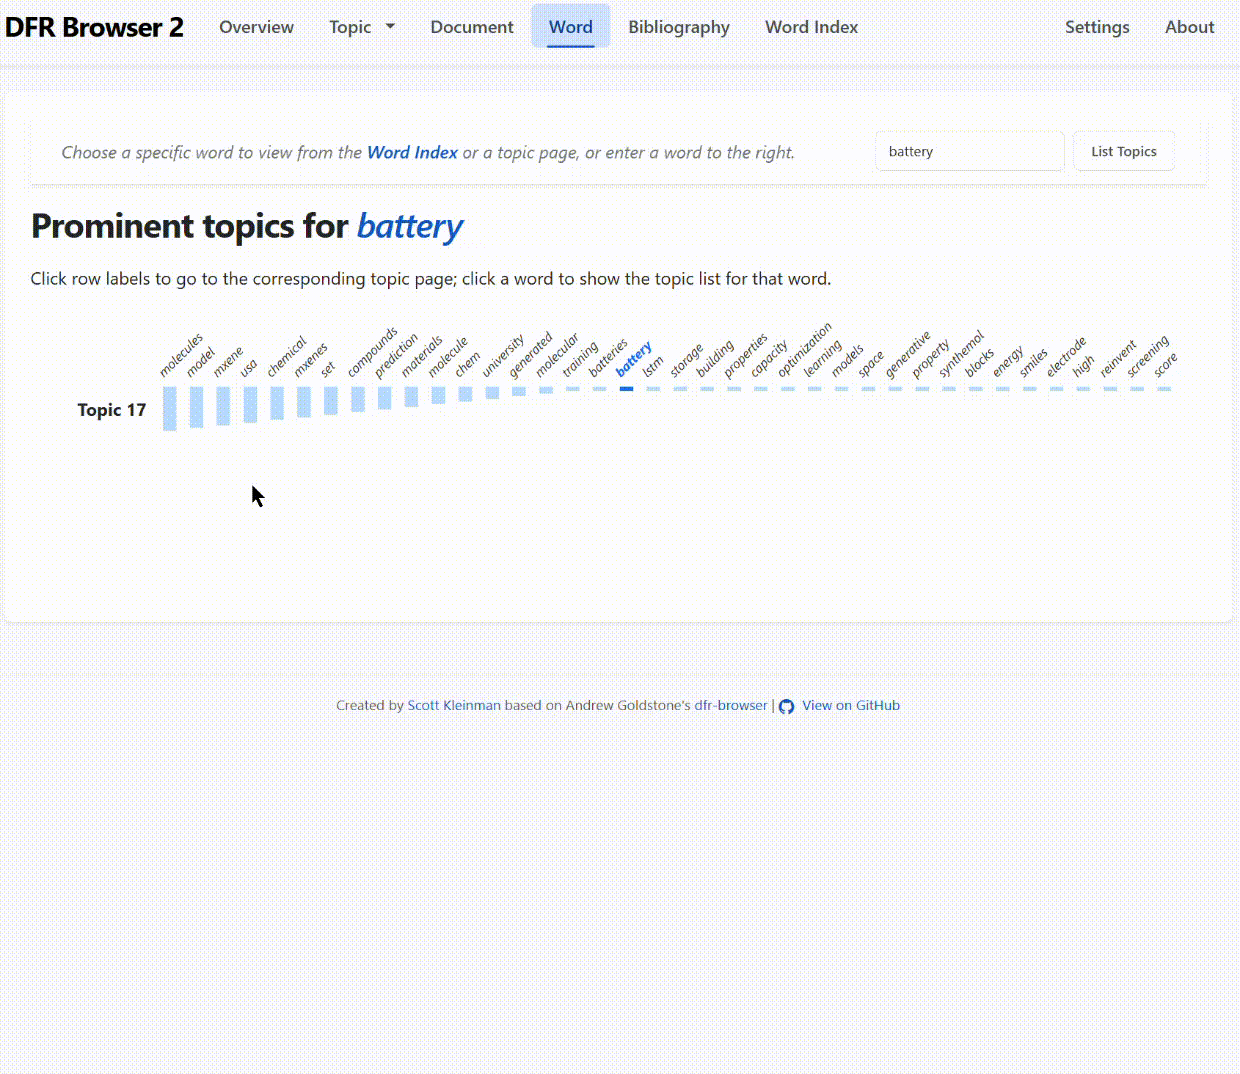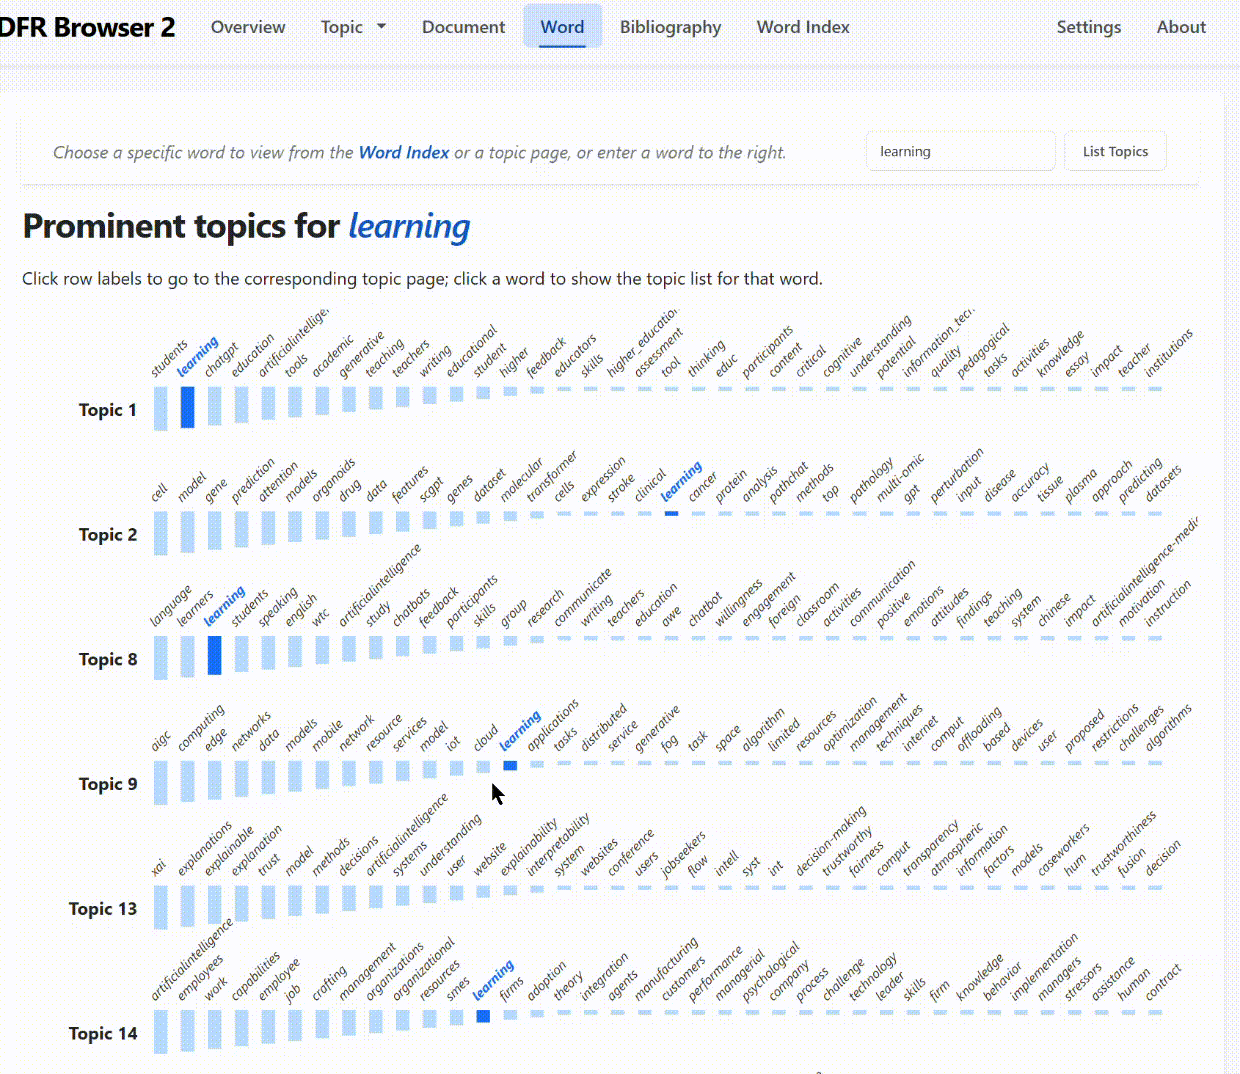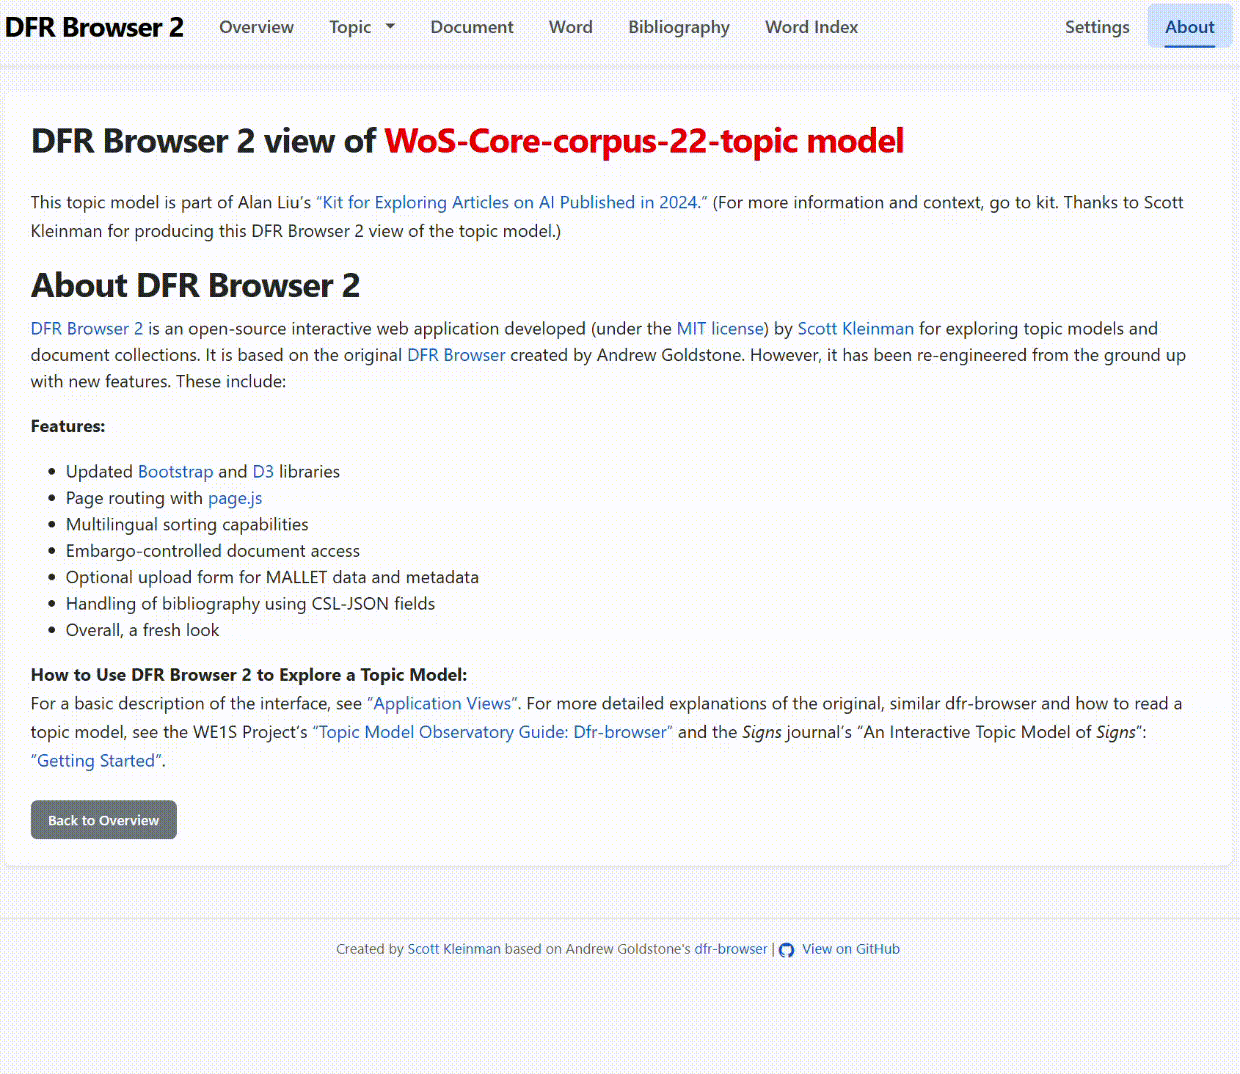
Interactive visualizations provide higher-level abstractions facilitating interpretation. I recommend the DFR Browser 2 visualizations to general users as the most intuitive and full-featured.
Animated gif of Dfr Browser 2. (Click links at left for actual Dfr Browser 2 views of topic models)
|
| 3 |
Word Embeddings: Interactive visualizations for exploring GloVe word embedding models fine-tuned on my corpora. Interface allows for finding nearest neighbors of words and analogies |
Folder 3 Readme:
Self-contained Web pages that open locally in a browser (takes a minute to load):
Each subfolder also contains a separate word_vectors.txt file with the embedding data along with a model_parameters.txt file.
|
The visualizations of word embeddings are fun to explore. They will be gee-whiz for those new to embedding spaces, where words are placed according to mathematically high numbers of relations with other words—all simplified for visualization in 3D. Users can search in the interface for words and their nearest embedding neighbors.
Animated gif of visualization of word-embedding model. (Click links at left for actual model visualizations.)
I used Anthropic’s Claude AI to code the visualizations of the embedding data.
|
| 4 |
Glossary of Epistemic Values: Glossary of epistemic values (positive and negative) mentioned in my two corpora, with frequency statistics and lists of ten nearest word-embedding neighbors of each word.
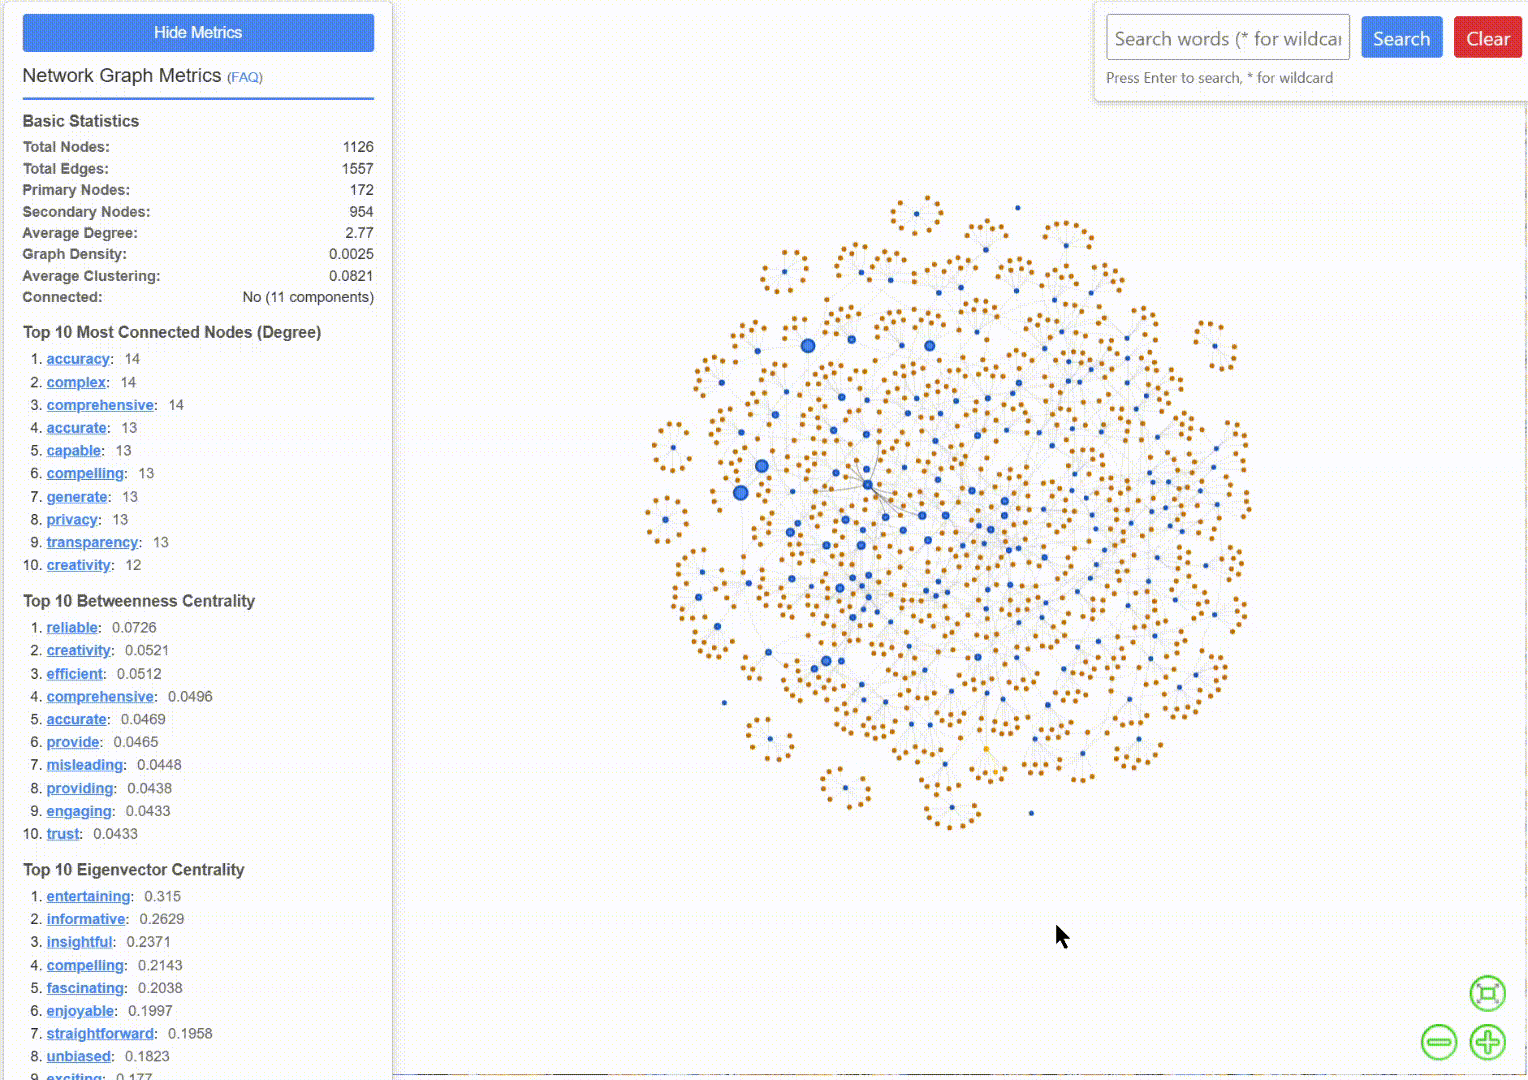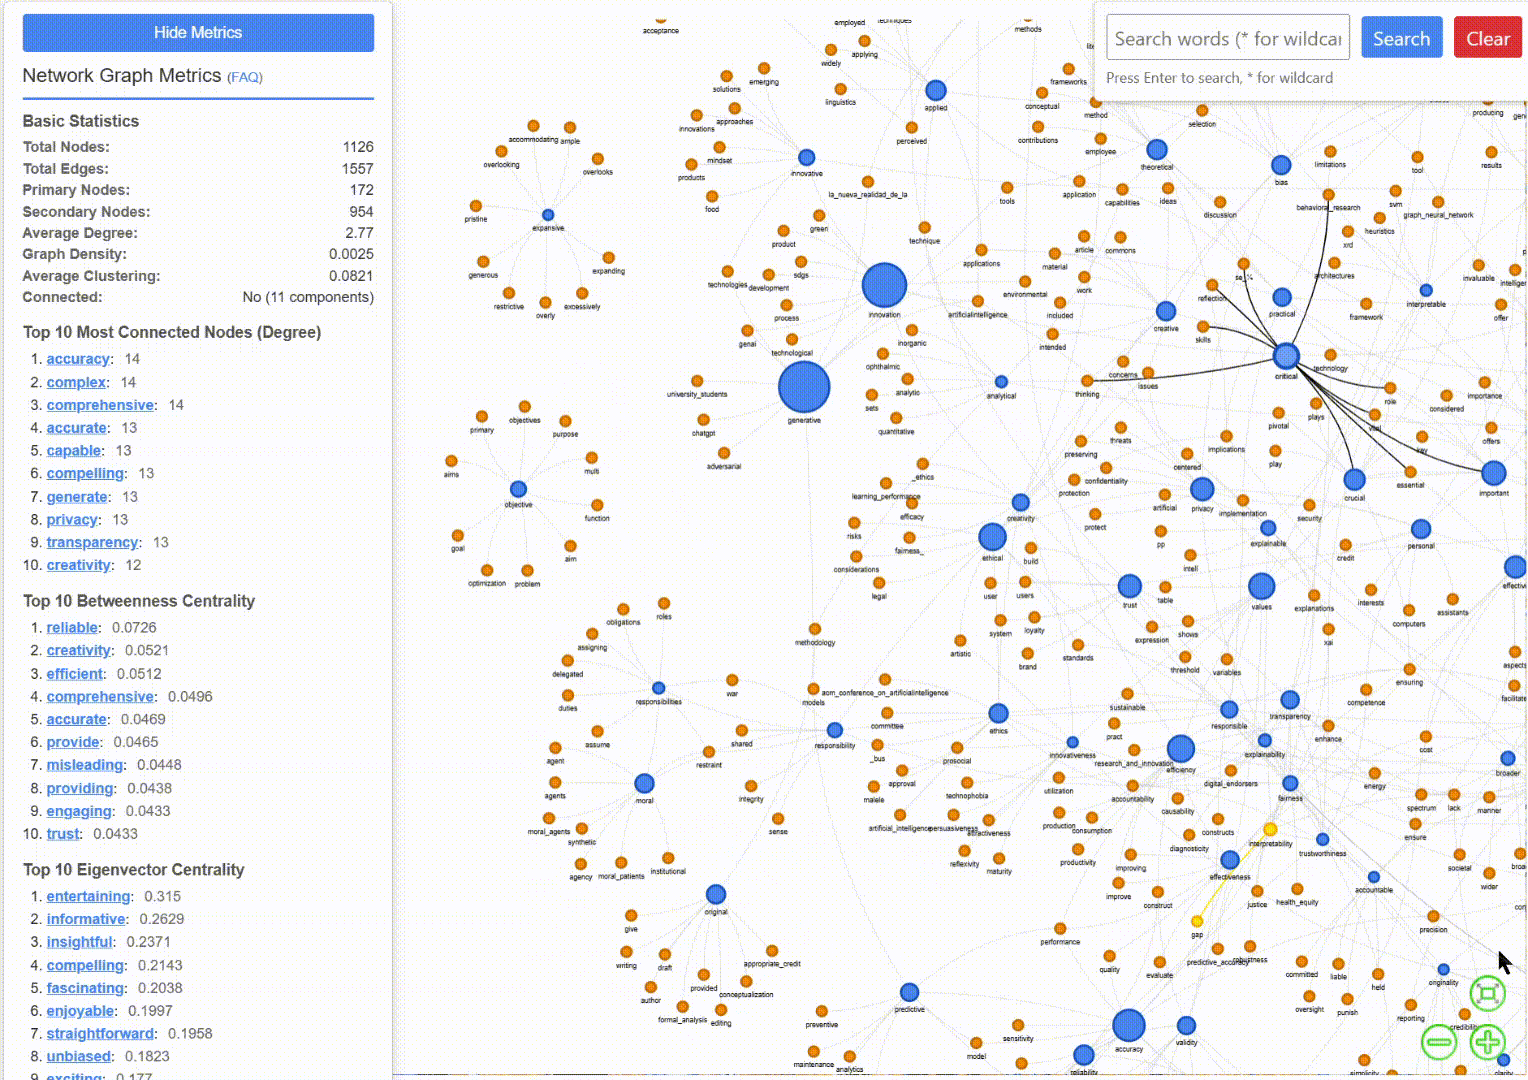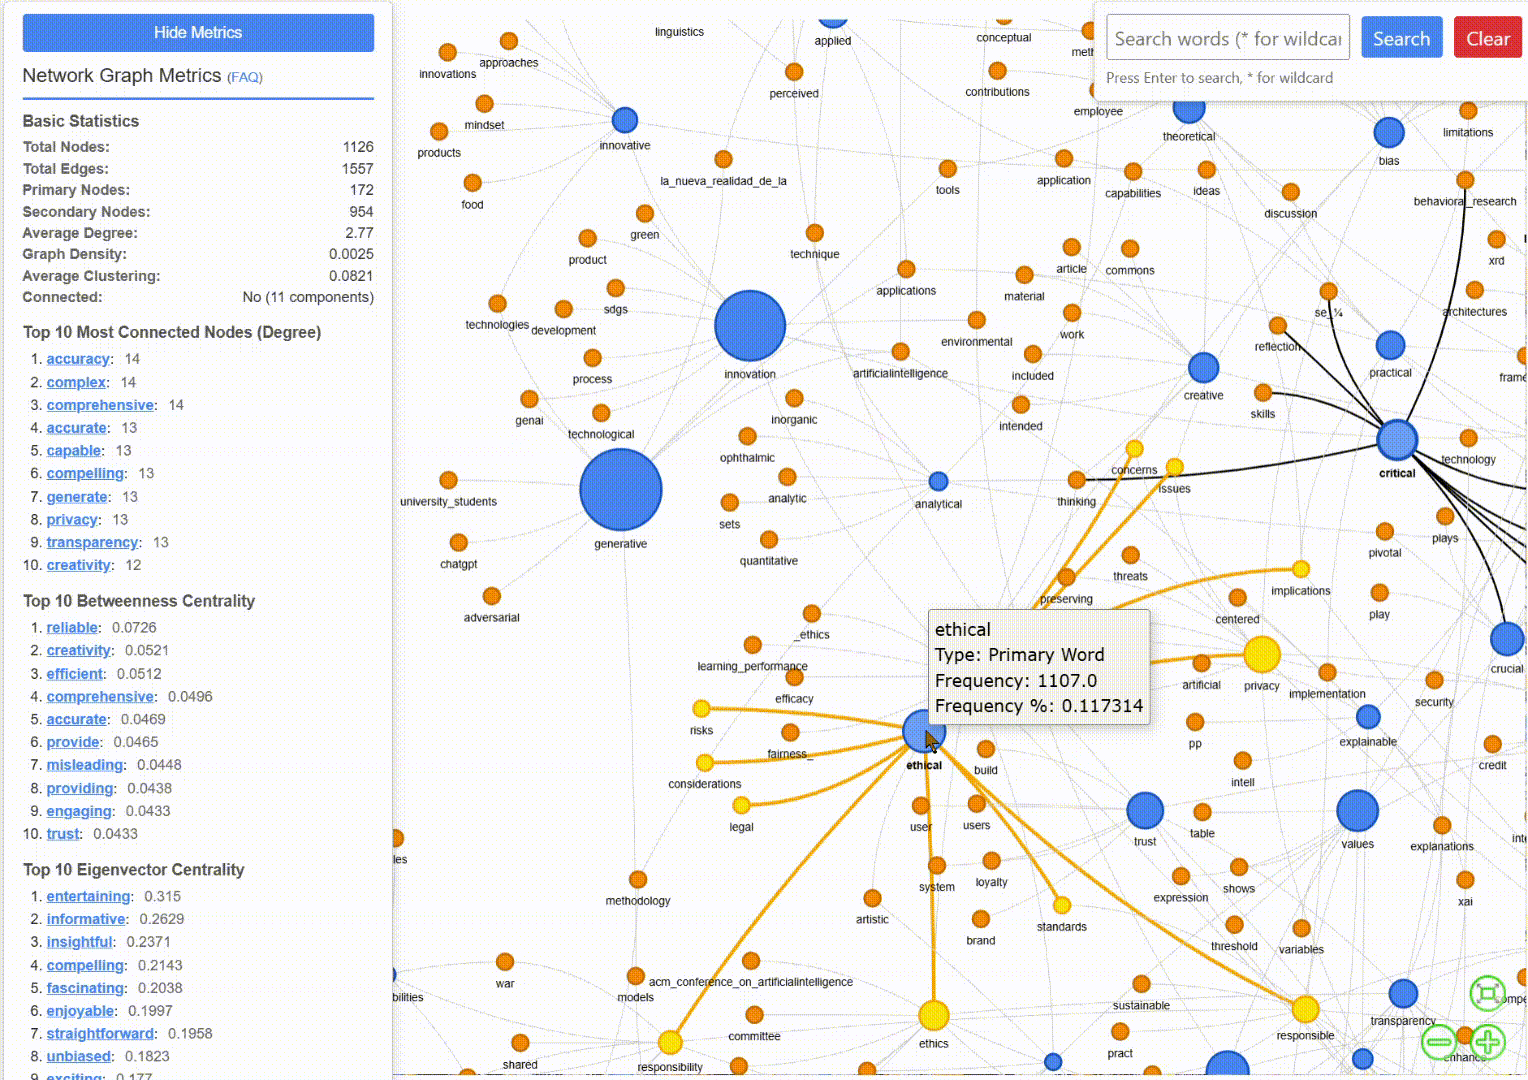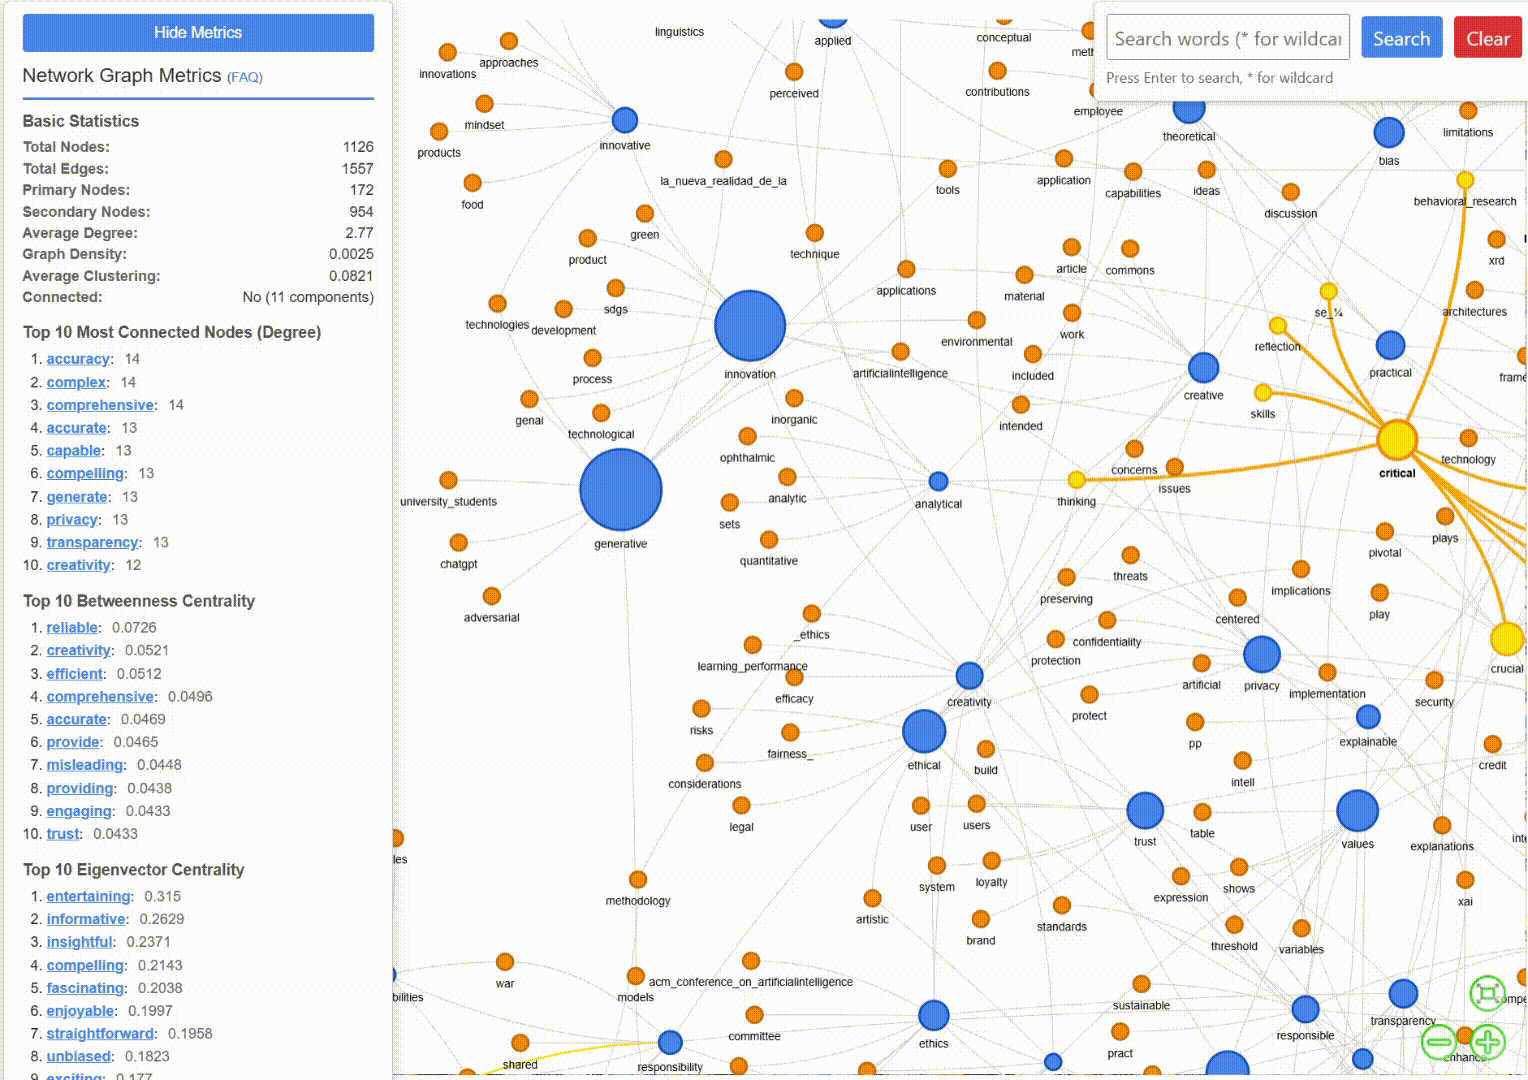
Also: Interactive word-net graph visualizations of the WoS Core and WoS AHCI words in the glossary
|
Folder 4 Readme:
Glossary in spreadsheet form:
Glossary visualized as interactive word-nets:
|
The glossary spreadsheet is the most informative, but the web pages with interactive graphs are the most fun.
Spreadsheet of epistemic values
|
Animated gif of interactive word-net of epistemic values (& word-embedding neighbors). (Click links at left for the actual word nets
|
I used Anthropic’s Claude AI to code my “word-net” visualizations.
Disclaimer: The glossary is a prototype or proof-of-concept because currently its less than 200 terms represent a partial harvesting of epistemic values that can always be added to and revised.
|
Additional Technical Information
I gathered word counts and other corpus-linguistics statistics with the assistance of Antconc (Anthony, AntConc (Version 3.5.7)). Topic models were created using Mallet (Mccallum). Interactive visualizations of topic models were created using DFR Browser 2 (Kleinman) and pyLDAvis (Mabey). Word embeddings were created using GloVe (Pennington et al.), which I implemented with the assistance of Python scripts created for my custom purposes with the assistance of Claude Opus 4.0 and 4.1 (Anthropic). Interactive visualizations for exploring word embedding models and word-net graphs were made with Python scripts also created with the assistance of Claude Opus 4.0 and 4.1.
Limitations of Kit
This kit is a prototype proof of concept developed for my article “AI Virtue: What is Good Knowledge in the Age of Artificial Intelligence?,” which suggests how to map the discourse of epistemic values swirling around generative AI (Liu).
A fully developed kit of this sort would be based on data from many more research articles and other materials discussing AI, and would require more fully evolved tools and collaborators from different fields. The limitations of the present kit include the following:
- Corpus design: I used highly cited articles from the Web of Science (previously called “Web of Knowledge”) Core Collection index to get a broad sample of articles across domains and disciplines; and then I took another sample just from the Arts & Humanities Citation Index included as a subset of the WoS Core Collection so that I could compare humanities and arts articles, a key domain context for my discussions of creativity, against the most highly cited articles in fields like medicine and business (among which humanities and arts articles would otherwise be a slim minority). A different project that would be just as interesting, but not one I have undertaken (at least not yet), would be to design a corpus that includes highly-cited articles from both the Web of Science’s Core Collection index and its relatively new Preprint Citation Index. That would allow me to compare the broad sample of discussions of AI against preprints in arXiv and elsewhere, which are skewed toward technical or other specialized fields or, even when originating from or intended for the humanities and arts community, are characterized by technically advanced approaches in the digital humanities, cultural analytics, new media studies, and so on. This would make sense, for example, if one wanted to see what the gap or lag is between the broad sample and research at the leading edge of AI research. (My thanks to Richard Jean So for prompting this line of thought. He pointed out that preprints, as opposed to published articles, are the leading edge of research on AI.)
- Date, language, and other constraints: A limitation of this kit is that it models data from only hundreds of articles published in a single recent year—not many thousands of articles from many years. It also deals with articles only in English, and articles only from research journals. Each of these constraints has implications for what can, and cannot, be inferred from using the kit. For example, the kit would ideally model many years of materials to allow for longitudinal study of the discourse of epistemic value before and after the advent of LLMs. And it would also ideally use at least one broader or different set of materials (e.g., articles randomly chosen from research on any topic) as a reference corpus allowing for “keyness” analysis (as corpus linguistics calls it) of statistically unique words in materials about AI.
- In-progress “Glossary”: Another limitation is that in reporting on epistemic values, I harvested terms for a glossary (kit folder 4) that is always in progress and thus only partial. More terms can be added. And more forms of each term can also be added, based on systematic sifting of “word families” (see Bauer and Nation; Anthony, WordFamilyFinder, Ver. 1.0.1). In additional stages of work, we would also want to edit the terms to cull, consolidate, standardize, and otherwise edit based on systematic methods of qualitative analysis, ideally in collaboration with many domain experts across fields.
- No user access to full texts: Copyright restrictions prevent me from including in the kit of any tool or data that contains full text from articles. The kit contains only “non-consumptive use” data such as word lists, statistics, or embedding parameters.
- Pre-processing and processing decisions: the kit builds in interpretive and technical judgement calls I made at many levels—e.g., assumptions about how to preprocess texts to deal with compound phrases, named entities, and acronyms (I converted “artificial intelligence” and/or “AI” to “artificialintelligence,” for instance); what to add to a stopwords list of too-common words and proper nouns; how to balance optimization criteria in choosing the number of topics in topic models; which word embedding method to use (ultimately, I implemented a GloVe word embedding “fine tuned” on my WoS article sets); which similarity measure to use for finding nearest embedding neighbors (I chose cosine similarity), and how to avoid “over-fitting” to specific studies or language habits in the research journals.
The kit is a prototype that would benefit from improvement by others more seasoned in natural language processing, applied linguistics, and other fields who may wish to adapt it, or create their own version, for studying larger, more various corpora related to AI.
Notes
Web of Science’s
Core Collection contains its
AHCI index as one of its component subsets of citation indexes. As of Feb. 15, 2025, when I consulted Web of Science to establish the list of articles to study for my research, none of the articles on AI published in 2024 on AI that the Core Collection flagged as “high cited” were also in the AHCI index. However, lthe Core Collection index latter added
a few AHCI articles to its “highly cited” list (e.g., 10 articles as of Sept. 1, 2025).
My thanks to Scott Kleinman for early access to his DFR Browser 2, and for making the DFR Browser 2 visualizations of the topic models in my kit. These visualizations may be opened in a browser from my website through the links in this kit. But for users downloading my kit from its permanent, full-data deposit as a .zip file who wish to run the DFR Browser 2 visualizations locally on their computer, the procedure is as follows (requires the ability to run the Python script included here with DFR Browser 2, or to use other means in a command-prompt window, to start a local web server [localhost] on a computer):
- Open bash on a Mac, or a command prompt, Powershell, or other command terminal in Windows that has access to Python.
- Navigate to the folder containing the index.html file of the DFR Browser 2 of the desired topic model. (“cd [path to folder]”)
- Run: “python server.py” to start a local web server (the server.py script is included in the folder)
- Open a browser to “localhost:8000”, which will show the DFR Browser 2 visualization running in the local web server.
Alternatively, users can upload the DFR Browser 2 folders in my kit to an online web server (e.g., to their own website).
Works Cited
- Anthony, Laurence. AntConc (Version 3.5.7). Waseda University, 2019, https://www.laurenceanthony.net/software/antconc/.
- ———. WordFamilyFinder, Ver. 1.0.1. n. d., https://laurenceanthony.net/software/wordfamilyfinder/.
- Anthropic. Claude Opus 4.1. 2025, https://www.anthropic.com/claude/opus.
- Bauer, Laurie, and Paul Nation. “Word Families.” International Journal of Lexicography, vol. 6, no. 4, 1993, pp. 253–79, https://doi.org/10.1093/ijl/6.4.253.
- Kleinman, Scott. DFR Browser 2. 16 Oct. 2025, JavaScript, HTML, Python. 2026, GitHub, https://github.com/scottkleinman/dfr-browser2.
- Liu, Alan. “AI Virtue: What is Good Knowledge in the Age of Artificial Intelligence?”, Modern Fiction Studies (forthcoming).
- Mabey, Ben. “pyLDAvis 3.4.1 (Python Port of R Package by Carson Sievert and Kenny Shirley).” PyPi, 23 Apr. 2023, https://pypi.org/project/pyLDAvis/.
- Mccallum, Andrew Kachites. “Mallet: MAchine Learning for LanguagE Toolkit.” Mallet, 2002, http://mallet.cs.umass.edu.
- Pennington, Jeffrey, et al. “GloVe: Global Vectors for Word Representation.” Stanford Natural Language Processing Group, Aug. 2014, https://nlp.stanford.edu/projects/glove/.